Social Media Analytics: Complete Guide to Tracking Performance
Last Updated: September 16, 2026
If you’ve ever sat in a leadership meeting and watched a CMO’s eyes glaze over at a slide full of follower counts, you already know the problem with most social media reporting. I notice followers, likes and impressions look good in a screenshot but they do not tell anyone whether the marketing budget is actually working. Between saying “we posted a lot this month” and saying “here is the revenue we can link to social ” many brands lose the thread entirely.
That gap is exactly what social media analytics is supposed to close. Done properly, it’s not a dashboard full of vanity numbers — it’s a disciplined process of collecting, cleaning, and modeling the enormous volume of unstructured data that people generate every time they post, comment, share, or scroll past something without engaging at all.
There is a lot of it. As of 2026, DataReportal’s latest global social media statistics put the number of social media user identities worldwide at around 5.79 billion — roughly two-thirds of the planet., depending on which snapshot you look at. Almost two thirds of the planet. Every one of those social media users accounts is a source of text, images, video and behavioral signals arriving continuously and without structure. Making sense of that stream, and turning it into something a finance team will actually sign off on, is the real job of social media analytics.
This guide walks through the full picture: how the data is classified, which formulas separate real performance from noise, how sentiment analysis actually works under the hood, what the data pipeline looks like, and where the field runs into trouble — including the sarcasm problem nobody’s fully solved and the zero-click search shift that’s rewriting what “visibility” even means.
What Is Social Media Analytics? Foundations and Data Types
Social media analytics at its heart means gathering information from websites tidying it and using math or machine learning to pull out useful bits such, as trends, mood scores, predictions or suggestions. Social media analytics lives between data science and marketing plans, which’s why social media analytics often goes wrong: data workers create models that marketing people cannot understand while marketing people ask for numbers that no one can really compute accurately.
A framework for thinking about “big” social data
Academic literature on the topic often borrows from the broader “Big Data” framework, commonly summarized as the 5 Vs:
- Volume — the sheer scale of the data. Let me put this in perspective. IDCs Global DataSphere research said the world made or duplicated 64.2 zettabytes of data in 2020. That number of data will rise to 181 zettabytes of data by 2025. That growth, in data is a 23 percent yearly increase.. Social platforms are a meaningful contributor to that curve.
- Velocity — how fast the data arrives. A breaking news event or a viral post can generate hundreds of thousands of mentions within hours, which is very different from analyzing a quarter’s worth of customer emails.
- Variety — the mix of formats: text posts, images, video, audio, metadata, geotags.
- Veracity — how trustworthy the data actually is, given bots, coordinated inauthentic behavior, and plain misinformation.
- Value — whether any of this converts into something an organization can act on.
Some researchers take this idea further. Call it a “Sunflower” framework. They add parts. Like intelligence, infrastructure, service and how it affects the market. To explain not just the technical side of data but also its bigger economic and social role. You don’t have to remember the words. What is important is the idea: the amount of data alone is not the same as useful intelligence and most of the work is, about bridging that gap.
How social data actually gets classified
It helps to think about social analytics along three separate axes, because conflating them is where a lot of reporting confusion starts.
By data type:
| Analytics Type | What It Analyzes | Typical Format |
|---|---|---|
| Text Analytics | Posts, comments, reviews, captions | Structured & unstructured |
| Image Analytics | Photos, visual brand mentions, object recognition | Unstructured |
| Audio Analytics | Podcasts, voice notes, spoken mentions | Unstructured |
| Video Analytics | Video content, on-screen text, scene detection | Unstructured |
By purpose:
| Analytics Type | What It Answers |
|---|---|
| Descriptive | What happened? (post-mortem reporting) |
| Diagnostic | Why did it happen? (correlating variables) |
| Predictive | What’s likely to happen next? |
| Prescriptive | What should we actually do about it? |
By task:
- Visual analytics – Dedicated visualization machines to examine social data, such as identifying aggregations or outliers that a spreadsheet might mask.
- Web analytics – traffic and referral tracking, log driven analytics that link social activity with on site activity.
Text analytics remains the workhorse of the field — it shows up in the overwhelming majority of published research and commercial tools, mostly because language is still the dominant format of social communication and because natural language processing has matured faster than image or video analysis. If you’re building out an analytics stack and have to prioritize, start with text.
Beyond Vanity Metrics: The Formulas That Actually Mean Something
Here’s the uncomfortable truth that most agencies won’t include in a pitch deck: follower count, page views and raw impressions are almost useless when looked, at alone. These numbers measure exposure, not engagement.. Exposure does not reliably connect to revenue. A single post can reach half a million people. Bring in no results at all.. Another post that reaches just 8,000 people in the right community can actually move the needle and generate real sales opportunities. It’s not about how many people see it. It’s about who sees it and what happens after.
What you truly want are ratios. Metrics that compare interaction, against some baseline because ratios reveal quality, not scale.
The core engagement ratios
Engagement Rate by Reach (ERR)
ERR = (Total Engagements ÷ Post Reach) × 100This isolates how good the content itself is, independent of how the platform’s algorithm decided to distribute it. Two posts can get identical reach and produce wildly different ERR — that gap is your creative signal.
Engagement Rate by Followers (ERF)
ERF = (Total Engagements ÷ Total Followers) × 100Useful mainly for external benchmarking, since reach data for competitors usually isn’t public but follower counts are. Treat this as a rough proxy, not a precise measure — it assumes every follower sees every post, which isn’t remotely true given how algorithmic feeds actually work.
Engagement Rate by Impressions (ERI)
ERI = (Total Engagements ÷ Total Impressions) × 100This measures efficiency relative to how many times the content was actually served, including repeat views by the same person — a slightly different lens than reach, which counts unique viewers.
Amplification Rate
Amplification Rate = (Total Shares ÷ Total Followers) × 100This is arguably the most honest advocacy metric you have, because a share is a much stronger signal than a like — someone is putting their own reputation behind your content.
Conversation Rate
Conversation Rate = (Total Comments ÷ Total Followers) × 100Measures how deep engagement is than just passive approval.
A post that has comments but few likes is often more valuable than a post, with many likes but few comments because engagement shows that people are really taking time to think and reply.
For context on what good engagement rates look like published benchmarks show that typical engagement rates on LinkedIn are 2–5 percent on TikTok can reach double digits in strong cases on Instagram usually fall between 0.4 and 3 percent and on Facebook organic typically stay below 1 percent. These numbers change by source and over time so treat them as a compass rather than a fixed rule. If your engagement rates are far outside these ranges, in either direction you should investigate the reasons before you report engagement rates.
Weighted engagement scoring
Not all interactions require the same amount of effort, so treating a like and a save as equivalent flattens out useful signal. A common approach is to assign weights based on the cognitive or social cost of the action:
Weighted Engagement = (1.0 × Likes) + (2.0 × Comments) + (1.5 × Shares) + (2.5 × Saves)The specific weights are a judgment call, not a fixed standard — adjust them to reflect what actually matters for your business. A retail brand might weight saves heavily because saving signals purchase intent. A media publisher might weight comments more, since discussion drives the kind of algorithmic distribution they care about.
Calculating full-cost Social ROI
This is where most reporting quietly falls apart. Teams calculate “ROI” using only ad spend as the denominator, which flatters the number and misleads leadership. A full accounting has to include labor, tools, content production, and agency fees — everything it actually costs to run the program.
Social ROI = [(Attributed Social Revenue − Total Social Investment) ÷ Total Social Investment] × 100Where Total Social Investment realistically includes:
- Paid media spend
- Salaries and contractor time for the people running the channels
- Software and analytics tool subscriptions
- Content production costs (design, video, photography)
- Agency or freelancer retainers
If you’ve never run this calculation with the full cost basis, brace yourself — the honest number is usually much less flattering than the ad-spend-only version marketing has been reporting. That’s uncomfortable in the short term, but it’s also the only version of the number that survives a serious finance review.
Sentiment Analysis and Net Sentiment Score: What the Numbers Actually Mean
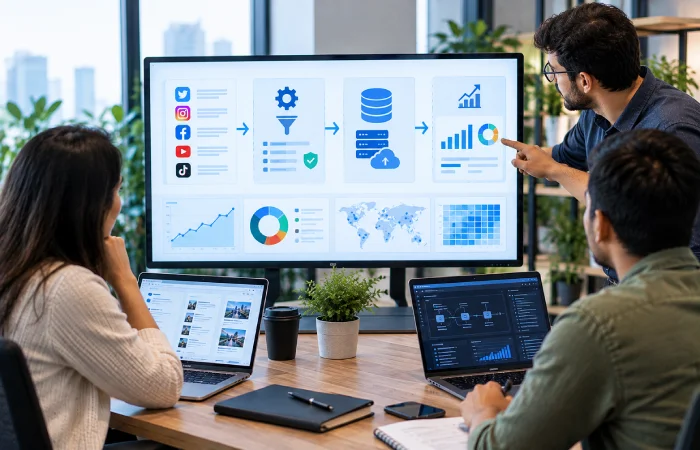
Engagement indicates that how much people are facing to your article. It doesn‘t mention if they enjoy viewing it. That’s where sentiment analysis comes in — and it’s more mathematically involved, and more prone to misuse, than most marketers realize.
How a single piece of content gets scored
At the most granular level, a document’s sentiment score is typically the average of the sentiment weights assigned to its individual words or tokens:
Sentiment Score = (sum of individual token weights) ÷ (number of tokens)I notice that every token receives a weight on a scale that usually goes from minus one point zero which means very negative to plus one point zero which means very positive. The document score is basically the average of those weights. I find that today’s methods vary from word lists for example VADER, to older machine learning classifiers such as Naive Bayes and Support Vector Machines and now even to transformer models like BERT and newer large language models, which understand context and negation much more accurately, than earlier systems.
A better version of this is Aspect-Based Sentiment Analysis (ABSA). It doesn’t just give a score, for the review or post. Instead it splits the text into parts. Like features or topics. And rates each one on its own. This way you can see what people like or dislike about each part of a product or service. A single review that says “the app’s design is beautiful but customer support never responds” isn’t neutral or mixed — it’s strongly positive on design and strongly negative on support, and ABSA is what lets you separate those two signals instead of averaging them into meaningless mush.
Net Sentiment Score — and why the formula you pick changes the answer
Net Sentiment Score (NSS) is a brand-health index often shown between -100 and +100 that shows how many positive mentions balance out the ones. But here is where it gets complicated there are two ways to calculate it and even with the same data it can produce very different results.
Take a sample of 1,000 classified mentions: 380 positive, 220 negative, 400 neutral.
Model 1 — Total Corpus (neutral mentions included in the denominator):
NSS = [(Positive − Negative) ÷ Total Mentions] × 100
NSS = [(380 − 220) ÷ 1,000] × 100 = +16.0
Model 2 — Normalized Opinion (neutral mentions excluded):
NSS = [(Positive − Negative) ÷ (Positive + Negative)] × 100
NSS = [(380 − 220) ÷ (380 + 220)] × 100 = +26.7
Same underlying data, two different scores, more than 10 points apart. Neither formula is “wrong” — they’re answering different questions. The Total Corpus model tells you the sentiment balance across everything people are saying, including the large volume of neutral, purely informational chatter. The Normalized model tells you, among people who actually expressed an opinion, how the balance skews. If your data has a lot of news that doesn’t show feelings (this often happens with big brands that get a lot of coverage) the Total model might not show how much your real fans really like you. If you are looking at scores from times or comparing with other companies the main thing is not to worry about which model is right. It’s better to choose one model and use it all the time. Changing models, in the middle of a report is how companies end up creating an idea of a trend.
As a rough, practical way to interpret an NSS number — treat this as a working framework rather than an industry-wide standard, since no single body governs these bands:
| NSS Range | Rough Interpretation |
|---|---|
| Below 0 | Negative sentiment currently outweighs positive |
| 0 to +20 | Mixed to neutral; limited differentiation |
| +20 to +50 | Generally healthy sentiment |
| Above +50 | Strongly positive — worth double-checking for selection bias before celebrating |
The owned-versus-earned disconnect
One of the more useful diagnostic exercises is separating owned sentiment (reactions to your official posts and campaigns) from earned sentiment (unprompted, organic conversation happening elsewhere). It’s entirely possible — common, even — for a brand to see glowing sentiment on its own channels while earned sentiment quietly deteriorates. That gap usually means people are being polite in your comments section while venting honestly somewhere you’re not watching as closely. If you only track owned sentiment, you’ll be the last to know about a real problem.
Similarly, watch what happens when Share of Voice (the percentage of category conversation your brand controls) rises at the same time NSS falls. That combination usually isn’t growth — it’s a controversy pulling more people into the conversation than usual, and it deserves a closer look before anyone reports the SOV increase as a win.
Data Infrastructure, API Limits, and the Zero-Click Search Shift
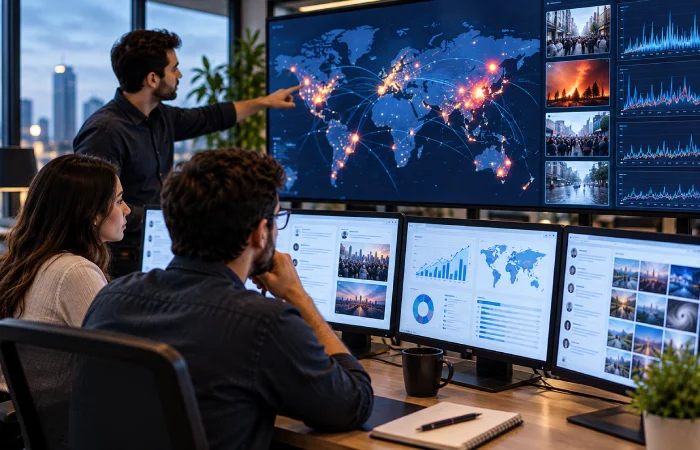
None of the formulas above matter if the underlying data pipeline is unreliable. This is the part of analytics that gets the least attention, in marketing-facing content and its usually where projects quietly fail.
A practical pipeline structure
Most functioning systems break down into four layers:
- Ingestion – extracting raw data via APIs, RSS feeds, or (traditionally however not today due to compliance issues) web scrapers.
- Cleansing and pre-processing [such as]deduplication, spam and bot filtering, language detection, tokenization.
- Storage — increasingly NoSQL and distributed storage rather than traditional relational databases, since social data doesn’t fit neatly into fixed schemas and needs to scale horizontally.
- Analytical engine — where NLP models, opinion mining, and predictive algorithms actually run against the cleaned data.
API access has gotten more restrictive, not less
If you built a social listening stack a few years ago and haven’t revisited it, some assumptions are probably stale. Reddit’s API, for example, enforces rate limits on free-tier OAuth clients — commonly cited around 100 queries per minute — and requires platforms to purge deleted user content within a defined compliance window. X API access has gone through commercial changes in recent years and the cost of large data access has gone up a lot. The practical implication is that you must plan for API costs and design a rate‑limit‑aware architecture as a budget line item, not just a side note. Also you should build in sampling or queuing logic of assuming that you can pull everything in real time.
Zero-click search and why it matters for social analytics
In February 2024, Gartner published a widely-cited prediction that traditional search engine volume would drop 25% by 2026 as generative AI tools increasingly act as substitute “answer engines.” That specific number has been debated since — some analysts argue it’s overstated, and independent checks in 2026 found that Google still commands the large majority of search market share even as AI referral behavior grows. What isn’t really in dispute is the direction of travel: zero-click search behavior — where users get their answer directly on the results page or from a chatbot and never visit a website — has become dramatically more common, with multiple 2026 industry reports putting zero-click rates in the 55–60% range for standard queries, and considerably higher when AI-generated overviews are present.
For social media analytics specifically, this shift matters in two ways. First, some of the same NLP and sentiment-scoring techniques used to analyze social conversation are increasingly relevant to understanding how brands get summarized and cited inside AI-generated answers — a discipline often called Answer Engine Optimization (AEO). Second, as fewer users click through to owned websites, social platforms and their embedded conversations become a relatively larger share of the places where brand perception actually gets formed and where it’s still observable in raw form. In other words, as web analytics gets murkier, social analytics becomes a more important early-warning system, not a less important one.
Real-Time Event Detection and Forensic Applications
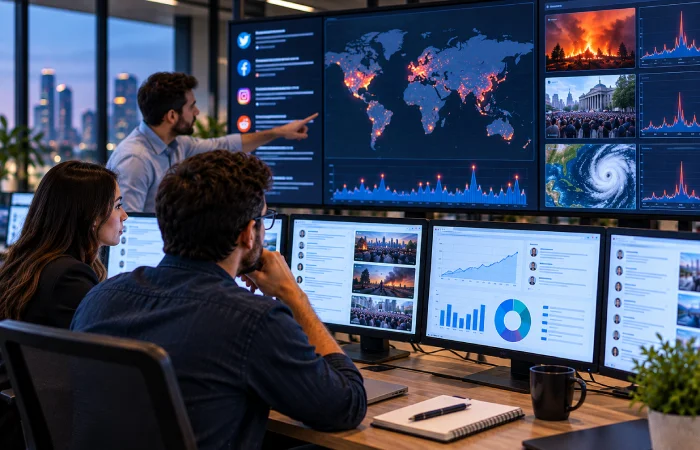
Most of what’s covered so far is about measuring ongoing performance. But social data streams are also used for something more urgent: detecting things as they happen, sometimes before anyone else has confirmed them.
New Event Detection (NED)
The workflow generally runs in three stages:
- Preprocessing — filtering out spam, bots, and profanity, then extracting metadata like named entities, hashtags, and geolocation.
- Detection — identifying that something is actually happening, using one of a few approaches: clustering methods (grouping similar posts together, often with algorithms like K-means or locality-sensitive hashing), term-based methods (watching for sudden spikes or “bursts” in specific keywords), or neural network approaches that use word embeddings and models capable of learning relationships between entities over time — including more recent graph neural network architectures designed to handle evolving, streaming data rather than a fixed snapshot.
- Post-detection — summarizing what’s being reported, ranking it for newsworthiness, and — critically — attempting to flag and debunk rumors before they spread further, since early social reports of breaking events are frequently wrong in some detail even when the broad strokes are accurate.
Organizations use this for crisis management, PR monitoring, and increasingly for identifying product issues before they show up in support tickets — a spike in specific complaint language on social often precedes a formal support surge by hours or days.
Forensic and investigative use cases
Outside of marketing, the same underlying techniques get applied in investigative contexts:
- Digital evidence corroboration — geotagged and timestamped posts can help verify or challenge witness timelines.
- Network mapping — graph theory methods are used to identify “bridge nodes” (accounts that connect otherwise separate clusters or communities) and map organizational hierarchies within coordinated networks, whether that’s a criminal syndicate, a disinformation campaign, or a coordinated inauthentic marketing operation.
- Behavioral risk assessment — aggregating linguistic patterns across a person’s public posting history, used cautiously and typically within a legal or law enforcement framework given the obvious privacy implications.
This isn’t a use case most marketing teams will ever touch directly, but it’s worth knowing it exists, since a lot of the underlying NLP and network-analysis tooling is shared infrastructure — the same graph algorithms that map a criminal network can map how your brand’s advocates and detractors are actually connected to each other.
Where the Field Still Breaks: Limitations and What’s Coming Next
Any honest guide to this topic has to include where it falls apart, because vendors selling analytics platforms have every incentive to gloss over the failure modes.
The recurring technical problems
- Sarcasm and irony remain genuinely hard for automated sentiment models. “Great, my flight got cancelled again” reads as positive to a naive classifier and negative to any human. Context-aware transformer models have improved this significantly but haven’t solved it.
- Negation scope — a phrase like “not bad at all” or “wouldn’t say I hated it” confuses simpler models that key off individual words rather than sentence structure.
- Mixed sentiment within a single post — someone can praise your product and criticize your shipping in the same sentence, and averaging that into one score erases the useful part of the signal, which is exactly why aspect-based approaches exist.
- Domain-specific jargon — sentiment models trained on general text often misread industry-specific language. In gaming communities, “sick” and “insane” are usually high praise. A generic model will flag them as negative.
Data quality and bias problems
- Demographic representativeness — social media users are not a random, representative sample of the general population. Platform demographics skew by age, geography, income, and political engagement in ways that shift over time, and any research or business decision built purely on social sentiment inherits that skew.
- Bot and coordinated inauthentic activity — synthetic accounts distort both raw volume and Share of Voice, and detecting them reliably remains an active, unsolved arms race between platforms and bad actors.
- Algorithmic amplification bias — platforms’ own distribution algorithms tend to favor high-arousal, controversial content, which means the conversation you’re able to observe is not a neutral sample of what people actually think — it’s a sample skewed toward whatever the algorithm decided to push.
Where this is heading
The clearest trend is convergence toward multimodal analysis — models that process text, image, audio, and video together rather than as separate pipelines, which matters increasingly as more social communication happens through video and voice rather than text. The practical implication for anyone building or buying an analytics stack: prioritize platforms and vendors that are investing in multimodal capability now, because text-only tooling is going to look increasingly incomplete as short-form video continues to dominate platform growth.
The other clear trend, discussed above, is the blending of social listening with search intelligence. Social data captures how people feel. Search data captures what people are actively trying to find or solve. Neither one alone gives you the picture. The organizations that are getting the value out of analytics right now are the ones that combine both. These organizations do not treat data and search data as separate departments, with separate budgets.
Frequently Asked Questions
What’s the difference between Engagement Rate by Reach (ERR) and Engagement Rate by Followers (ERF)?
ERR measures engagement relative to the unique users who saw the post, separating the quality of the content from the algorithm‘s decision to display it. ERF measures engagement against your total follower count instead, which is a rougher proxy but useful for competitive benchmarking since reach data usually isn’t public.
How do the Total Corpus and Normalized Opinion models differ when calculating Net Sentiment Score?
The Total Corpus model keeps neutral mentions in the denominator, which pulls the overall score toward zero — especially for brands with a lot of purely informational or news-based coverage. The Normalized Opinion model strips neutral mentions out entirely and looks only at the ratio between positive and negative opinions, which tends to produce a more extreme (and arguably more emotionally honest) number.
Why does text analytics dominate social media research and tooling?
Text remains the most common format of social communication, and natural language processing has simply matured faster and more affordably than image, audio, or video analysis. That’s shifting as multimodal AI improves, but text-based sentiment and topic modeling is still the most mature and widely deployed piece of the stack.
Does Answer Engine Optimization actually reduce the impact of falling organic click-through?
It helps offset it rather than eliminate it. As more people look for answers directly from AI‑generated summaries of clicking on links arranging your content— including social media posts and your own owned pages— so that AI systems can accurately cite and summarize it becomes an important way to keep your brand visible even if it does not bring back the traffic lost. I see this as an addition to regular SEO, not a replacement, for it.
What costs actually belong in a proper Social ROI calculation?
Beyond paid media spend, an honest calculation includes salaries or contractor fees for the people managing the channels, software and analytics tool subscriptions, content production costs, and any agency or freelance retainers. Leaving these out is the single most common way social ROI gets overstated in internal reporting.
Bringing It Together
None of this works as a checklist you run once. The brands that get real value from social media analytics treat it as an ongoing discipline: pick your engagement formulas and stick with them long enough to see trends, choose one sentiment methodology and apply it consistently, keep an honest accounting of what the program actually costs, and stay alert to the structural shifts — API restrictions, zero-click search, multimodal content — that quietly change what “good measurement” even means from one year to the next.
Creative marketing enthusiast sharing practical insights on digital growth, branding, and online strategies. Passionate about helping businesses succeed with simple, effective, and result-driven marketing solutions.